Deepak Kumar
Postdoctoral Researcher, AI Division, KDDI Research, Inc.

KDDI Research, Inc.
Fujimino, Saitama, Japan
I am a Postdoctoral Researcher in the AI Division at KDDI Research, Inc., Japan, where I work on Vision-Language-Action (VLA) models for robot manipulation.
I received my Ph.D. in Computer Science from IIT Roorkee, advised by Prof. Balasubramanian Raman, with a thesis on multimodal affect and behavior analysis. Before that, I was a research intern at Samsung Research Institute Bangalore, working on Vision-Language Models, and an Assistant Professor at GBPUAT Pantnagar.
My research interests include robot learning with VLA models, multimodal affective computing (audio, video, text, and physiological signals), and Vision-Language Models.
News
| Sep 20, 2026 | Serving on the Technical Program Committee of PerAgents 2027, the First International Workshop on Pervasive Agentic Systems and Multimodal Foundation Models, co-located with PerCom 2027, Goa, India. |
|---|---|
| Sep 15, 2026 | Serving as a Meta-Reviewer for CVIP 2026, the 11th International Conference on Computer Vision & Image Processing, NIT Calicut, India. |
| Jul 1, 2026 | Became a reviewer for IEEE Transactions on Multimedia (TMM). |
| May 25, 2026 | Attending FG 2026 in Kyoto, Japan, with registration and travel support from KDDI Research. |
| Apr 15, 2026 | Our paper VIBE: Disentangling Social Dynamics via Kinematics-Informed Variational Inference for Behavioral Emotion is accepted at ICML 2026, Seoul. |
Education
Ph.D. in Computer Science
Indian Institute of Technology Roorkee, Uttarakhand, India
• Dec 2021 – Jul 2025
Thesis: From Signals to Visuals: Multimodal Affect and Behavior Analysis
Supervisor: Prof. Balasubramanian Raman
M.Tech. in Software Engineering
Motilal Nehru National Institute of Technology Allahabad, Prayagraj, India
• Aug 2014 – Jun 2016
Supervisor: Prof. Rajesh Tripathi
B.Tech.
Uttar Pradesh Technical University, Lucknow, India
Work Experience
KDDI Research, Inc., Fujimino, Saitama, Japan
Working on Vision-Language-Action (VLA) models for robot manipulation.
Samsung Research Institute Bangalore (SRI-B), India
Worked on Vision-Language Models (VLMs).
Deloitte US-India Offices
College of Technology, GBPUAT, Pantnagar, Uttarakhand, India
Awards & Honors
- Dec 2024Travel Grant to attend the 5th Indian Symposium on Machine Learning (IndoML 2024), BITS Pilani Goa.
- Oct 2024Top-3 paper in the MultiMediate Challenge at ACM Multimedia 2024.
- Jun 2024Finalist, Qualcomm Innovation Fellowship India 2024.
- May 20242nd place (team lead, “Syntax”) in the Brain Responses to Emotional Avatars Challenge, IEEE FG 2024.
- Aug 2023First rank in the Data Science and AI Quiz by CommBank India at SocProS 2023, IIT Roorkee.
- Nov 2022Microsoft Research registration and travel grant to present at CVIP 2022.
selected publications
- ICML
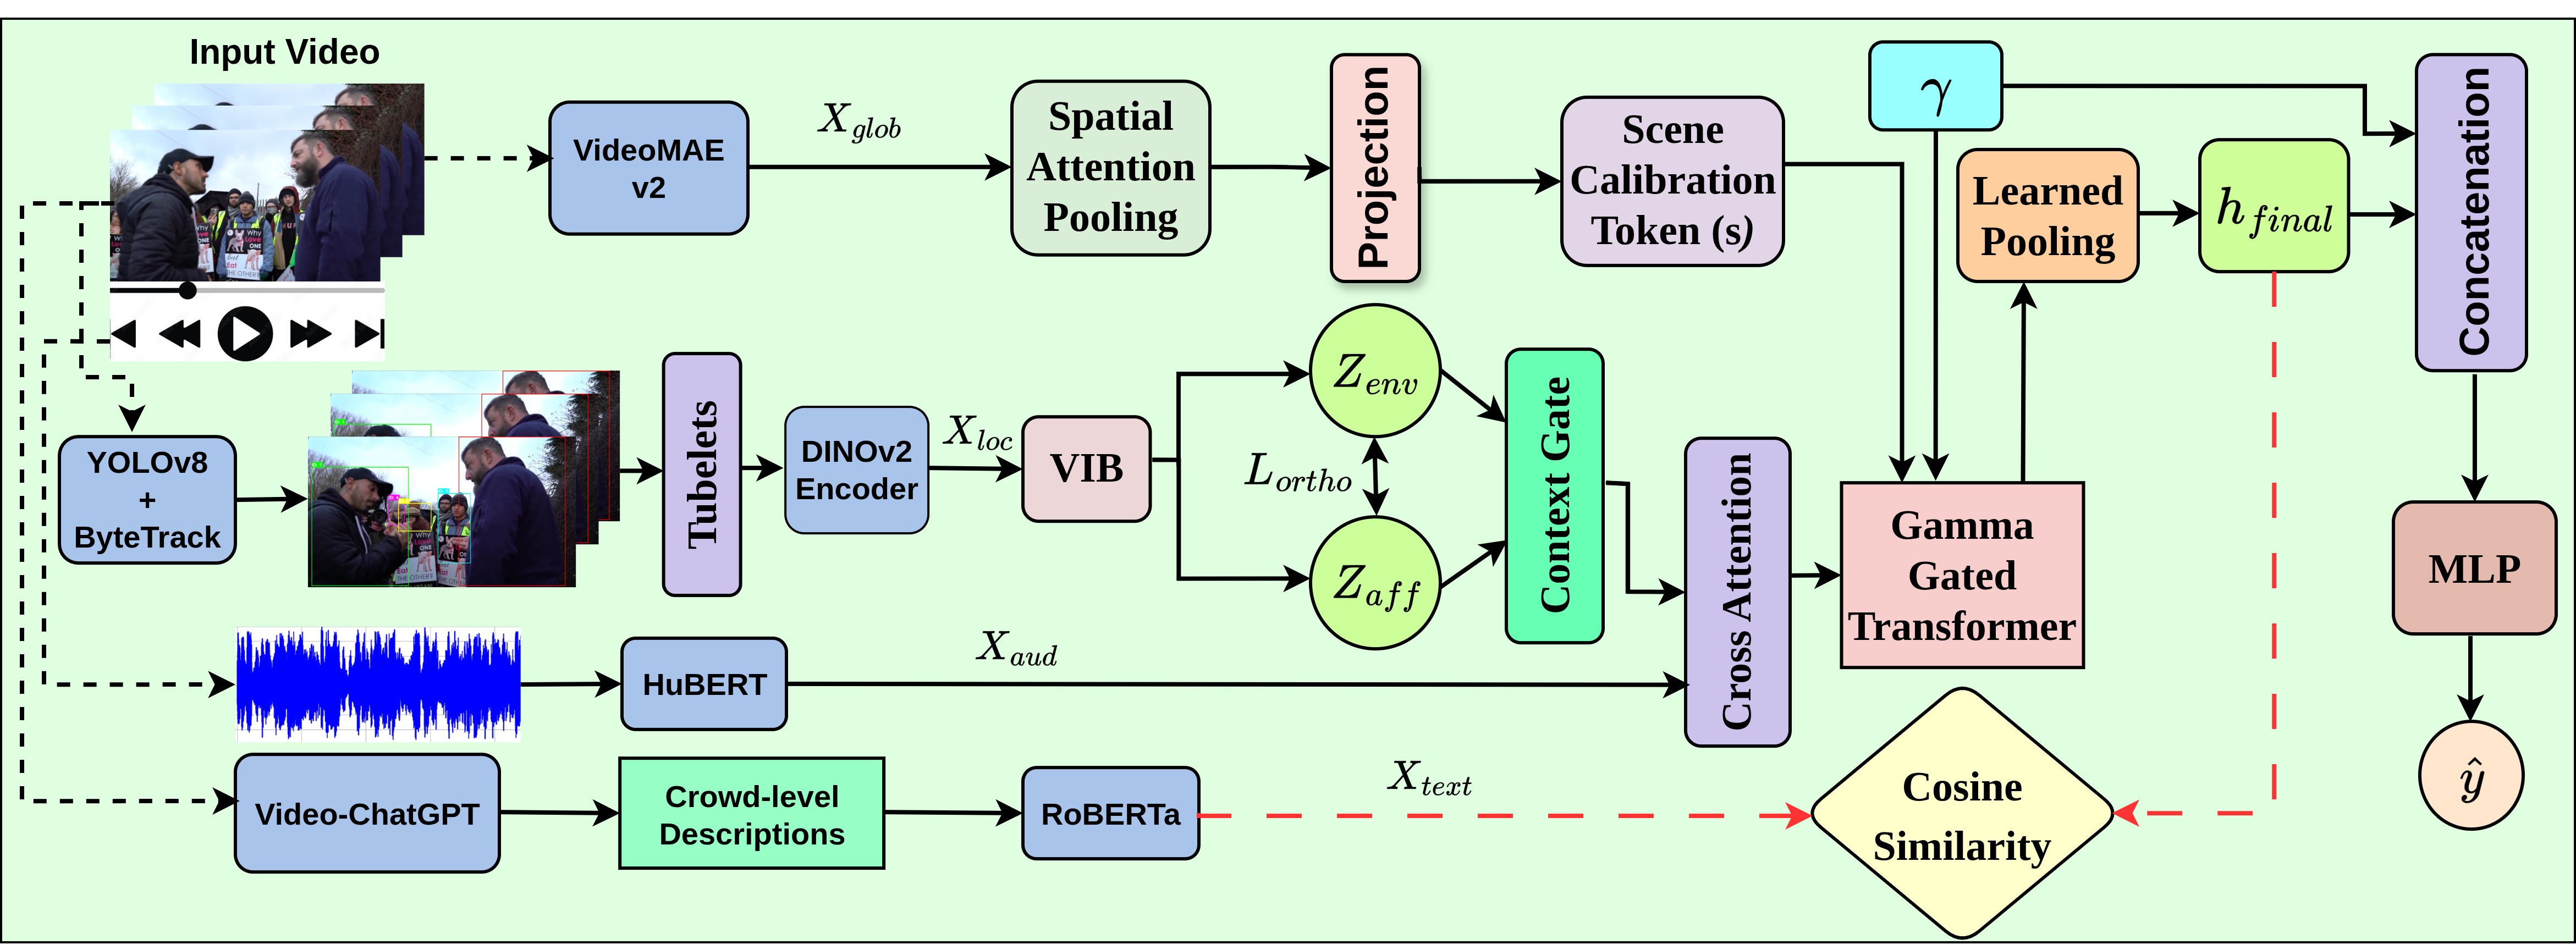 VIBE: Disentangling Social Dynamics via Kinematics-Informed Variational Inference for Behavioral EmotionIn Proceedings of the 43rd International Conference on Machine Learning (ICML), 2026
- ACM MM
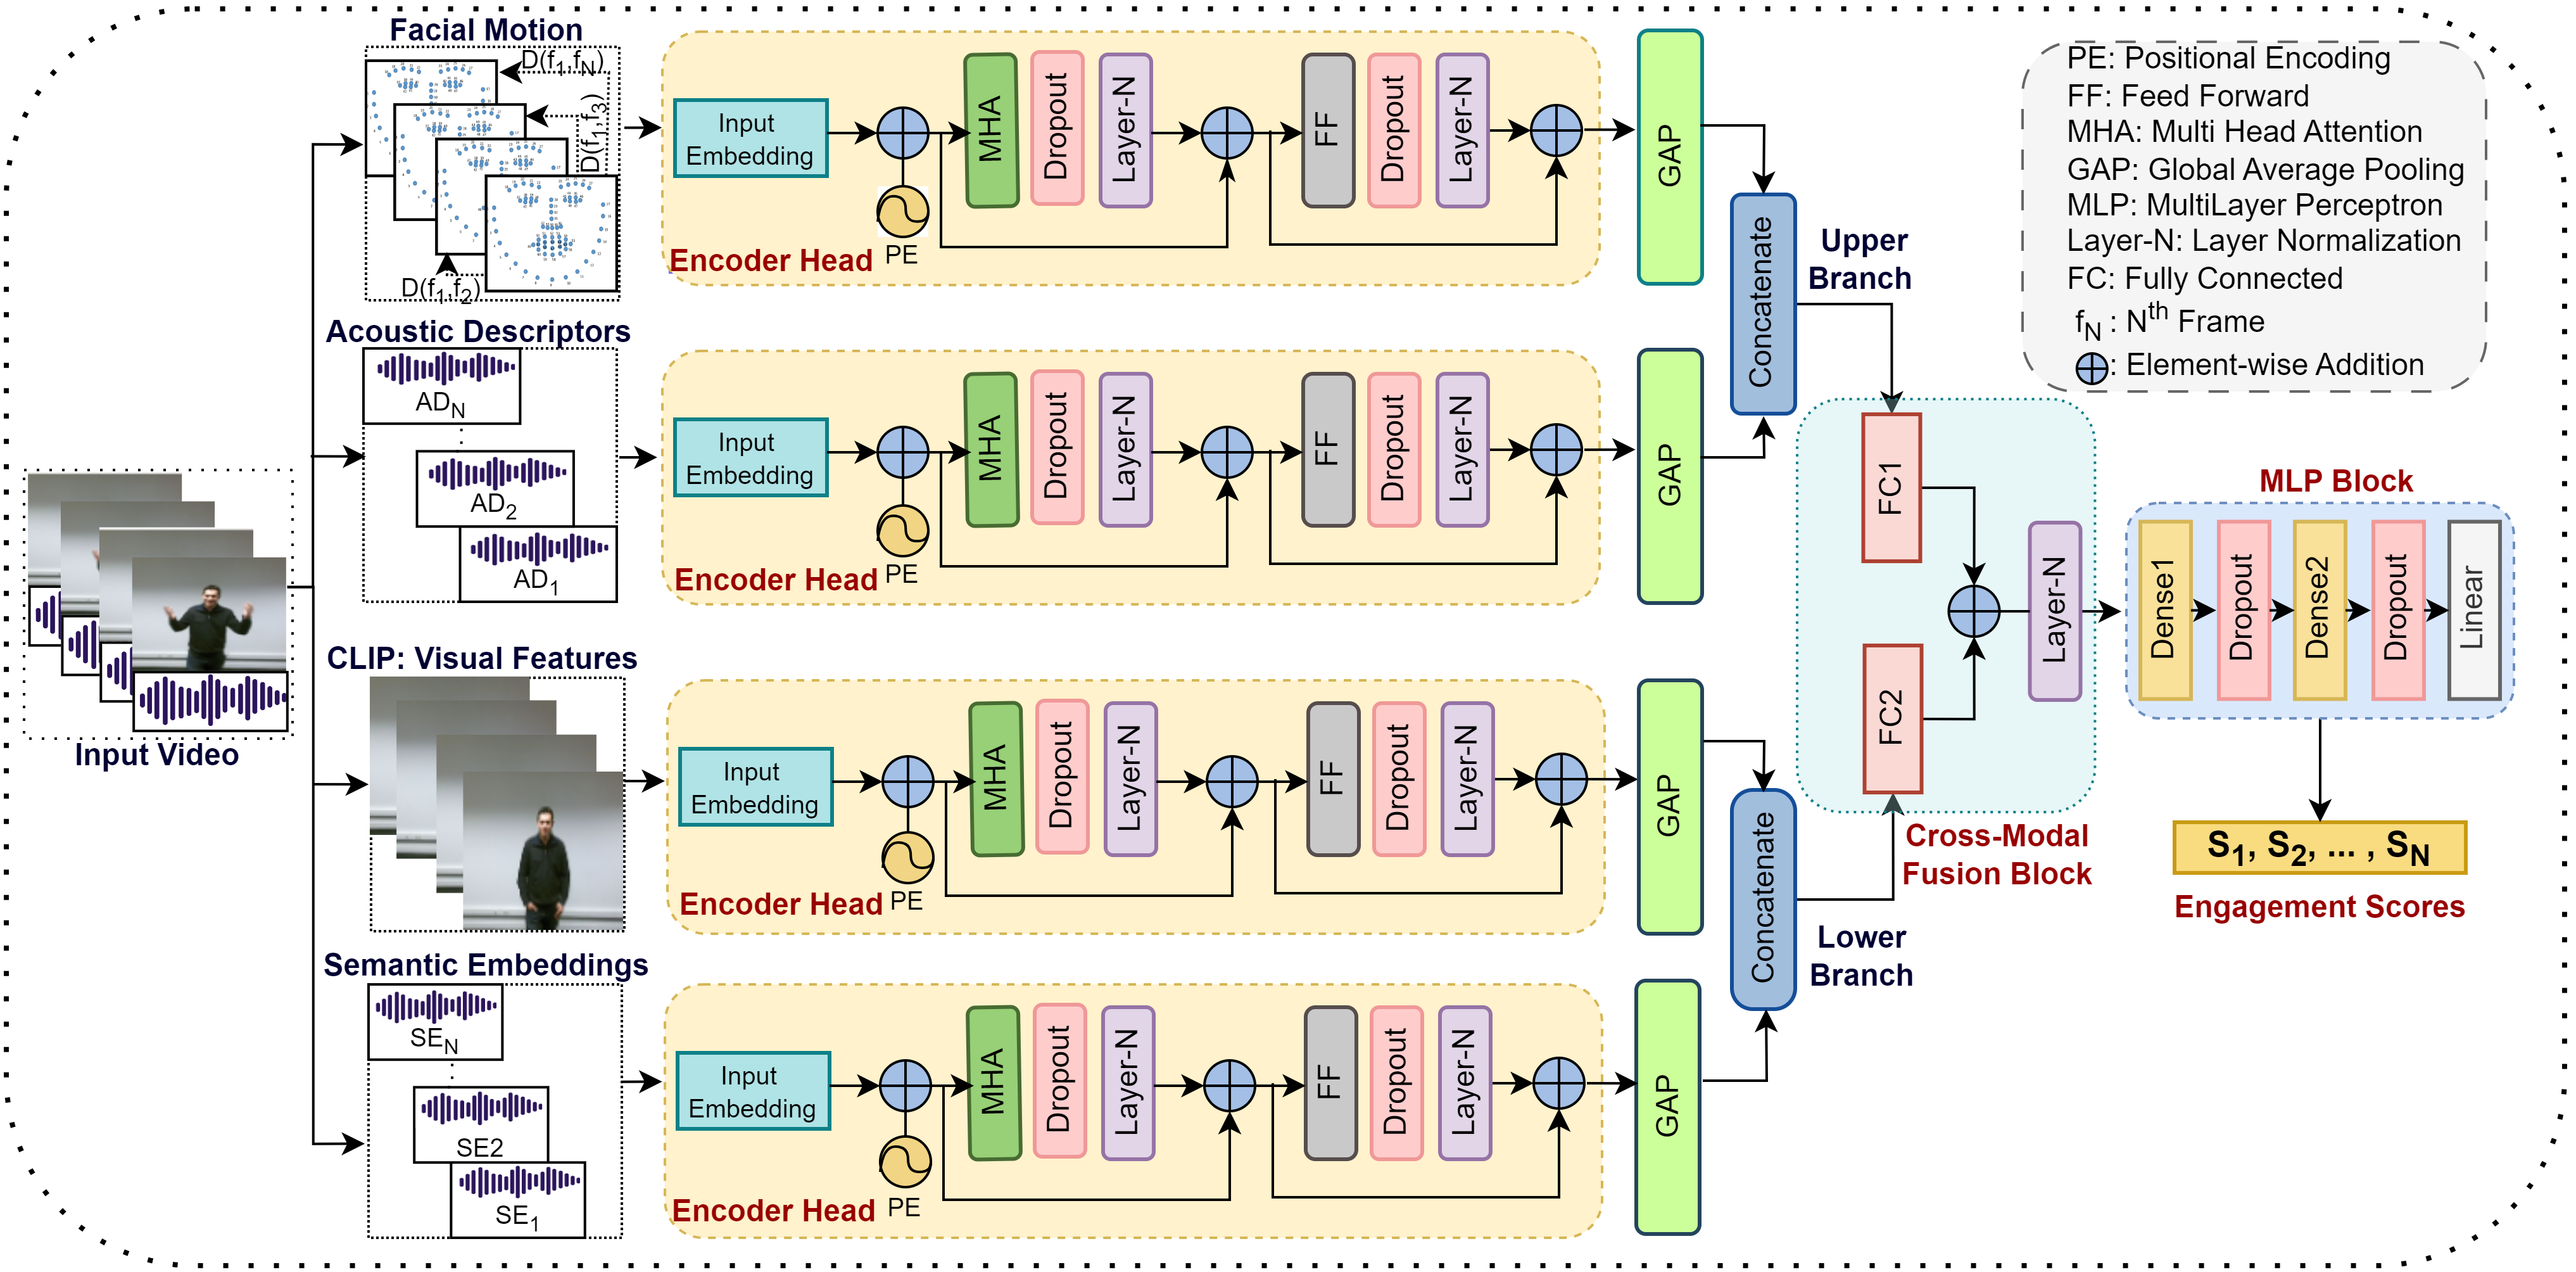 Towards Engagement Prediction: A Cross-Modality Dual-Pipeline Approach using Visual and Audio FeaturesIn Proceedings of the 32nd ACM International Conference on Multimedia (MM), 2024
- BSPC
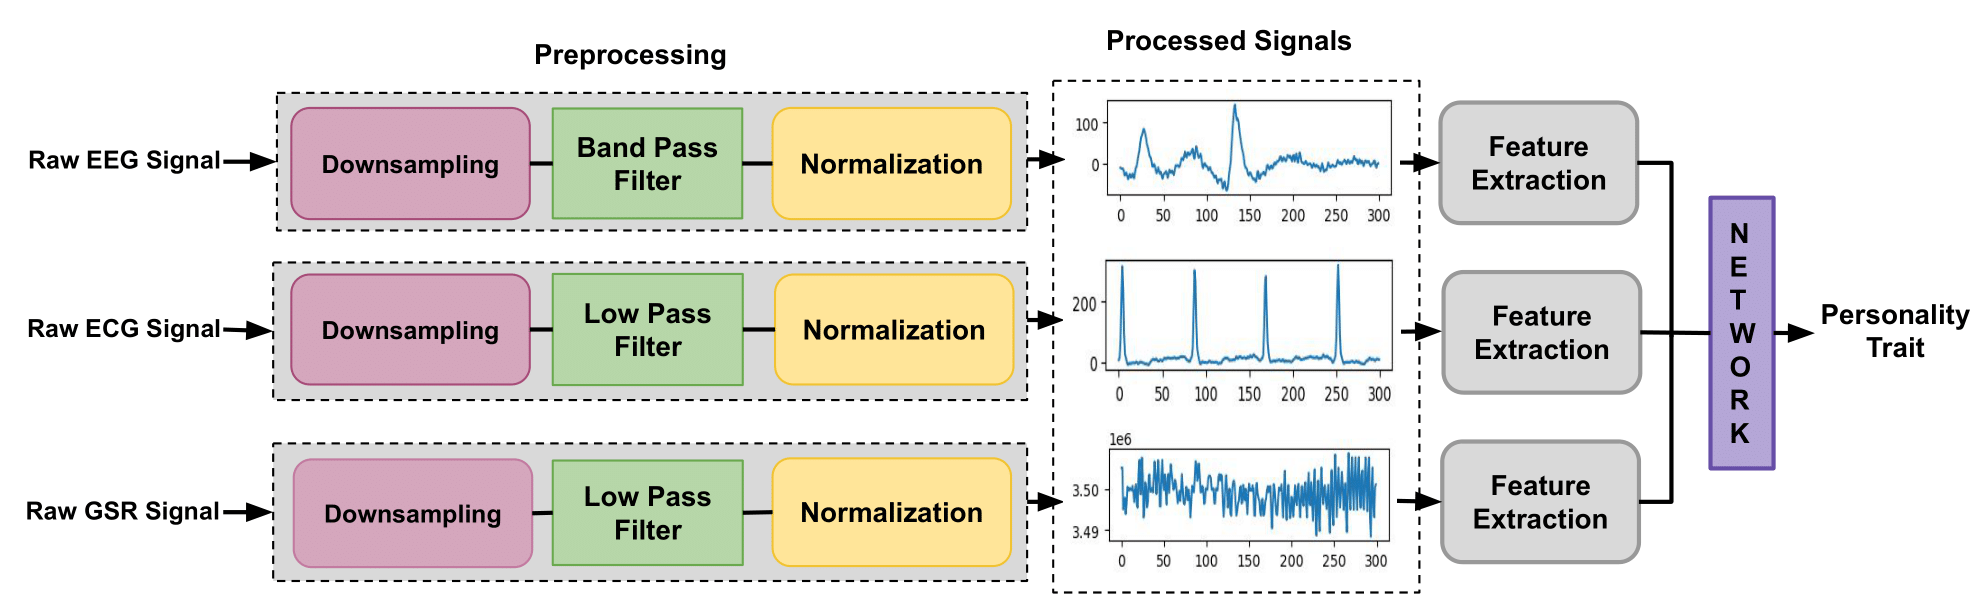 All Signals Point to Personality: A Dual-Pipeline LSTM-Attention and Symbolic Dynamics Framework for Predicting Personality Traits from Bioelectrical SignalsBiomedical Signal Processing and Control, 2024
Research Areas
Research details →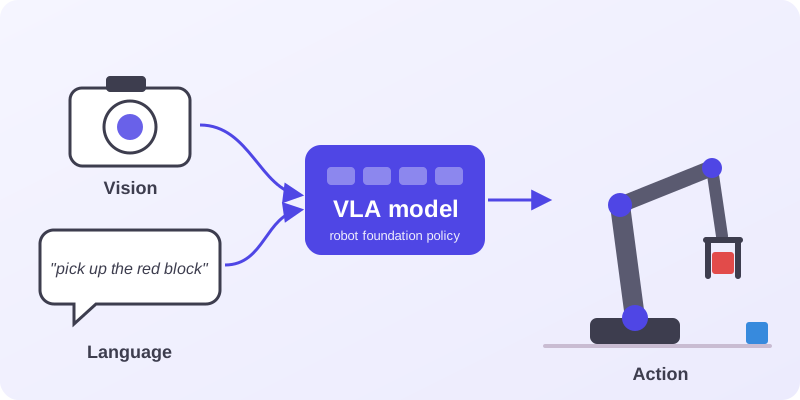
Vision-Language-Action Models
Adapting and evaluating robot foundation models for reliable real-world manipulation.
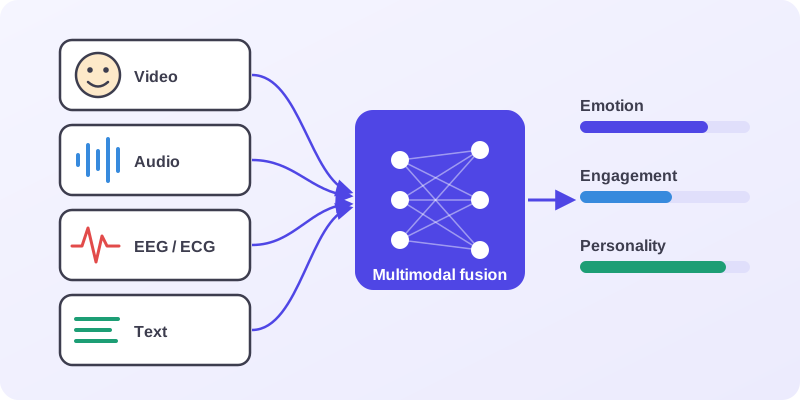
Multimodal Affective Computing
Emotion, engagement, and personality from video, audio, text, and EEG/ECG signals.
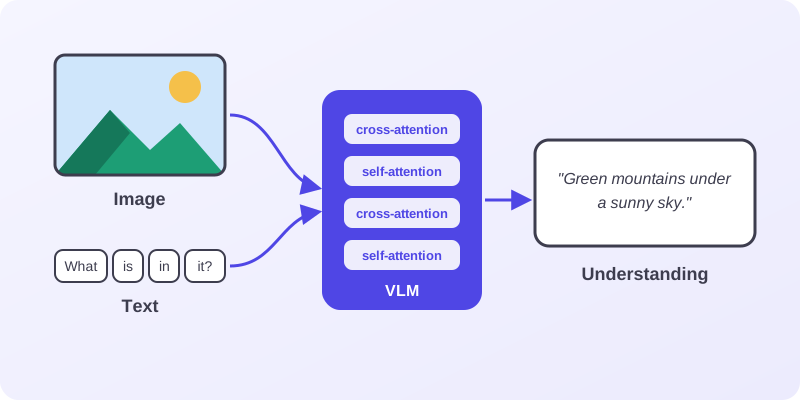
Vision-Language Models
Multimodal understanding that connects what a model sees with what it reads.