Research
My research spans robot learning and multimodal human behavior understanding.
Vision-Language-Action models for robotics
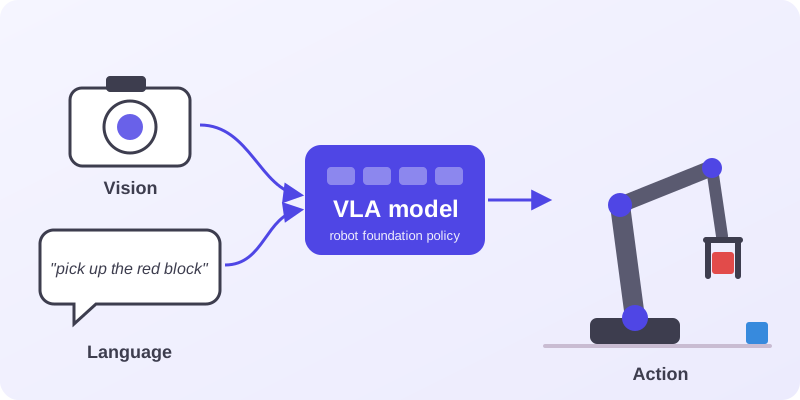
I adapt and evaluate robot foundation models on real manipulation platforms. My focus is on fine-tuning strategies, evaluation metrics that go beyond task success rate, and making policies more reliable at deployment. This is my current work at KDDI Research.
Multimodal affective computing
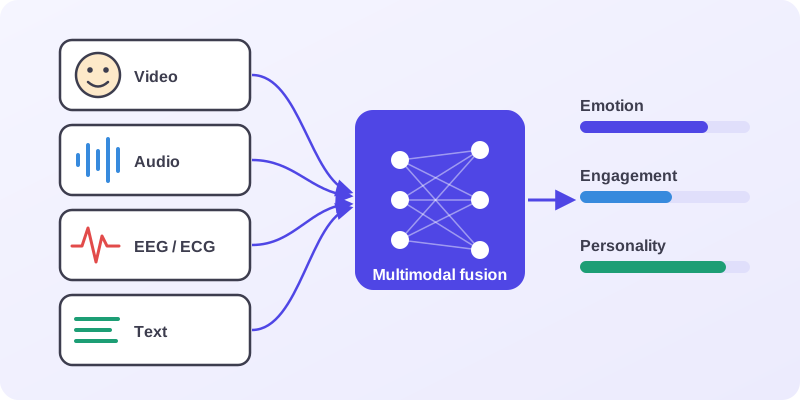
I model human emotion, engagement, and personality from audio, video, text, and physiological signals such as EEG and ECG. This line of work, developed during my Ph.D. at IIT Roorkee, has appeared at ICML, ACM Multimedia, ICPR, FG, and IJCNN, and in Elsevier BSPC.
Vision-Language Models
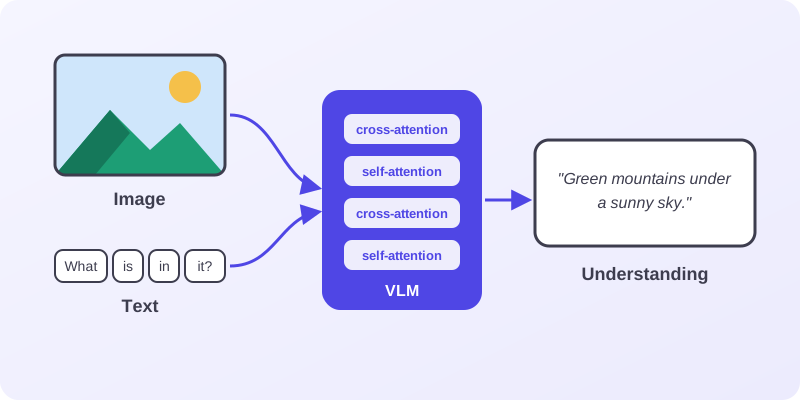
I work on multimodal understanding with VLMs, which I began during my research internship at Samsung Research Institute Bangalore.
See all papers on the Publications page.